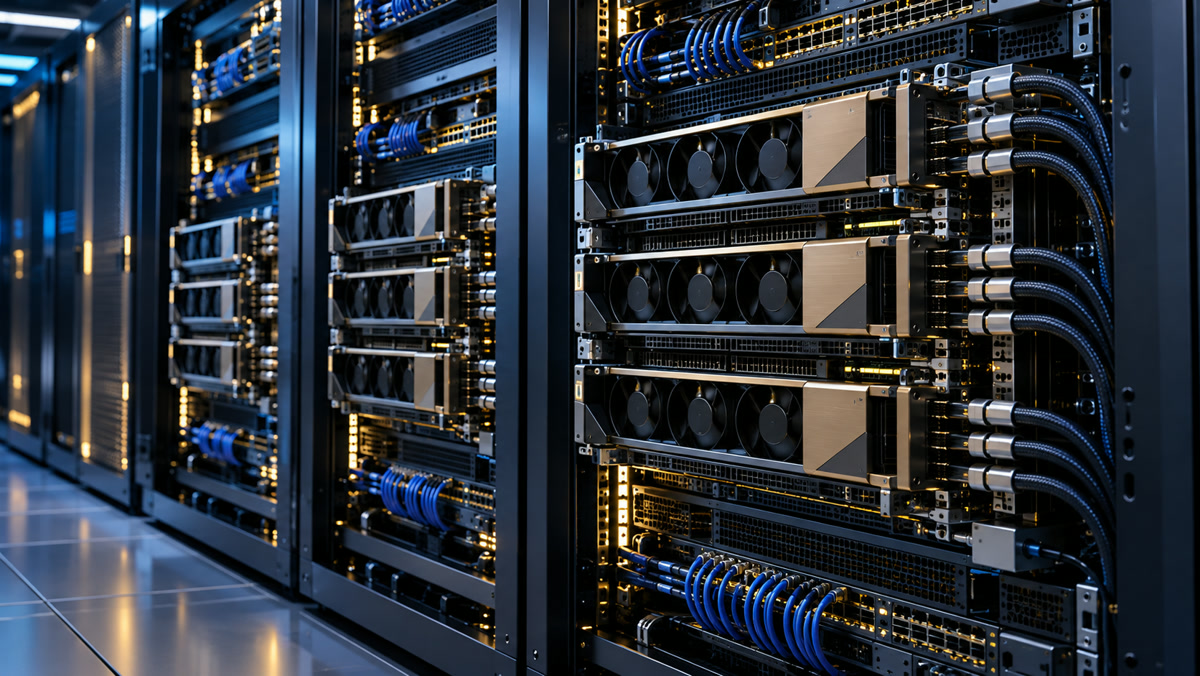
AI training & inference
GPU-dense systems, rack-scale platforms and clusters sized for model development, fine-tuning, retrieval, inference and accelerated analytics.
 Regional DevelopmentNetworks LLC
Request a Quote
Vendor-neutral configuration and integration support for corporate AI, industrial computing, HPC, private cloud and modern data-center platforms.
Plan your infrastructureRDN translates business, engineering and AI objectives into an executable infrastructure plan. We align compute, acceleration, memory, storage, networking, power, cooling, security and lifecycle support before equipment is selected.
Configurations are built around the application, data profile, service level, deployment environment and growth model—not around a single manufacturer catalogue.
GPU-dense systems, rack-scale platforms and clusters sized for model development, fine-tuning, retrieval, inference and accelerated analytics.
High-availability compute for ERP, databases, virtualization, VDI, private cloud, containers and business-critical applications.
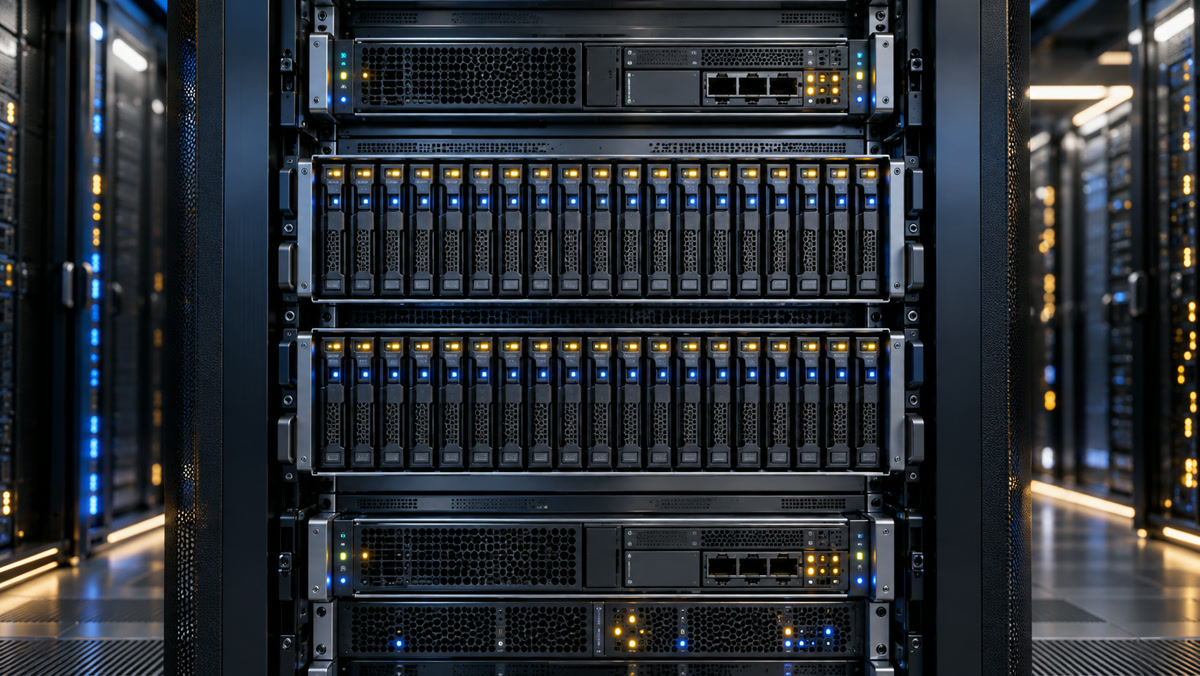
High-throughput file, object and block architectures with data protection, tiering, governance and recovery requirements defined.
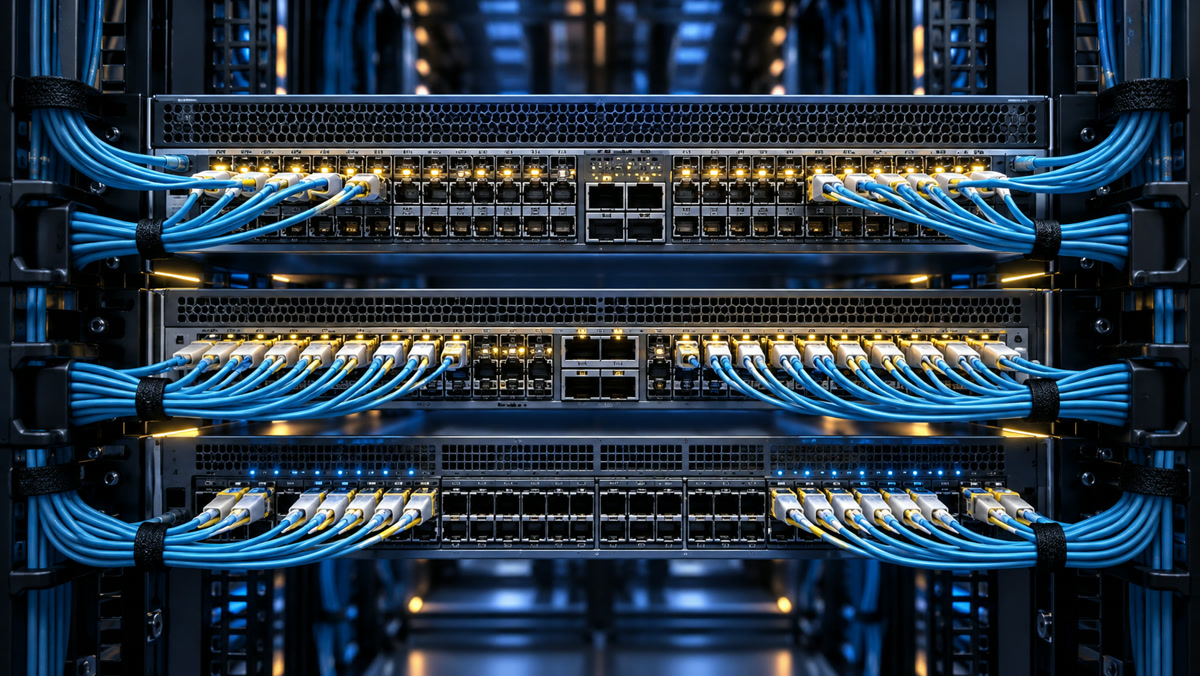
Low-latency Ethernet and accelerated interconnect design for east-west AI traffic, storage access, management and secure segmentation.
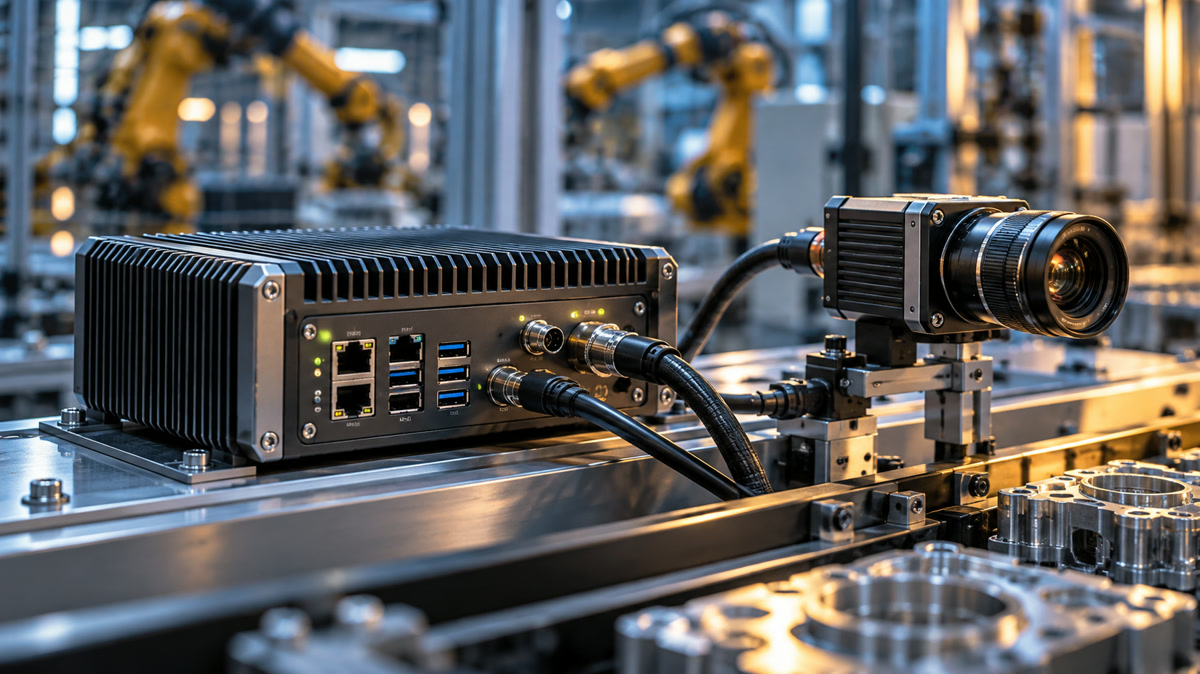
Rugged and compact systems for vision, automation, inspection, remote operations and low-latency inference near the source.
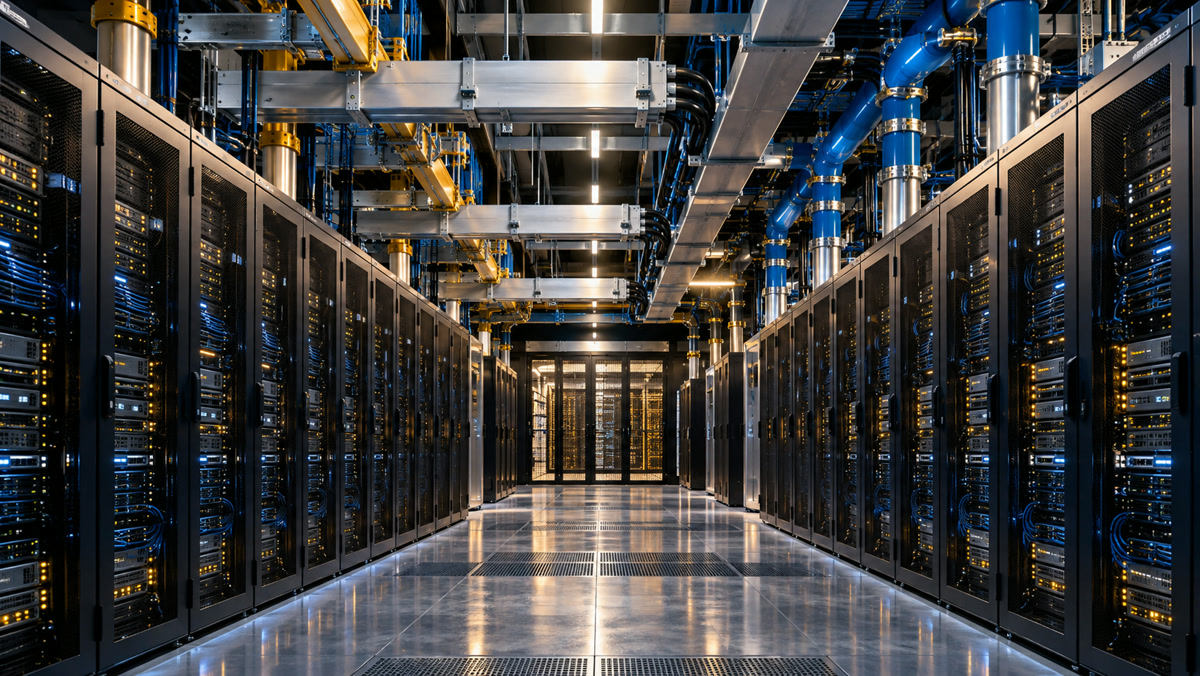
Rack density, redundant power, cooling, liquid-cooling interfaces, physical layout and deployment sequencing coordinated with the data center.
Accelerators alone do not determine results. CPU topology, GPU memory, interconnect bandwidth, storage throughput, software compatibility, power and thermals must operate as one validated platform.
Representative Supermicro pathway. GPU-optimized servers or rack-scale systems can be configured with NVIDIA accelerators, AMD EPYC or Intel Xeon host processors, high-speed fabric, AI-ready storage, redundant power and air or liquid cooling. Final selection follows the workload, site conditions and regional availability.
Each solution is scoped against measurable workload and operational requirements, with the freedom to compare complete OEM systems and best-of-breed component architectures.
Secure platforms for model serving, retrieval-augmented generation, fine-tuning and internal AI applications.
Parallel compute, simulation, scientific workloads, rendering and high-volume analytics.
Consolidated infrastructure for virtual machines, containers, VDI and critical business services.
Low-latency inference for manufacturing, logistics, inspection, security and remote facilities.
High-bandwidth data pipelines, scalable namespaces, protection and tiering for active and retained datasets.
Capacity planning, density migration, resilient network and power design, and cooling-readiness coordination.
The engagement can cover a focused system configuration or an end-to-end program—from workload discovery through supplier alignment, installation coordination and acceptance.
Define workloads, users, data, service levels, security and site constraints.
Model compute, storage, fabric, power, cooling and expansion requirements.
Evaluate validated OEM and component pathways against fit, lead time and lifecycle.
Coordinate supply, staging, documentation, logistics, installation and commissioning.
Plan monitoring, spares, support, upgrades, capacity and refresh cycles.
Representative manufacturers and platform providers considered across accelerated compute, enterprise servers, networking, storage and private-cloud infrastructure.
Manufacturer names and marks identify common technology ecosystems only. Their display does not imply that RDN is an authorized distributor, agent or partner. The list is representative rather than exhaustive; availability, support route, regional compliance and authorization are confirmed for each inquiry.